An AI research tool should not be judged by its best answer. It should be judged by whether another person can repeat the same task, inspect the evidence and understand why the result changed.
That sounds obvious, but most AI-tool comparisons still rely on a single prompt and a single screenshot. A polished response may look impressive while hiding unstable retrieval, missing papers, inaccessible citations or limits imposed by the free account tier.
This guide provides a practical seven-step test for comparing AI research assistants without cherry-picking successful runs. It is based on the AI News & Updates review methodology and our repeat-run work with ResearchRabbit, Elicit, Scite, Consensus and Undermind.
Important: AI research assistants can help with discovery and synthesis, but they do not replace a documented database search for systematic or safety-critical work. Treat generated summaries as starting points, not evidence.
Why one successful AI search proves very little
Traditional database searching is not perfectly static—the underlying index changes as new records are added—but the query itself can usually be documented precisely. AI research assistants add several more sources of variation:
- The system may rewrite a natural-language question differently on each run.
- Semantic retrieval and reranking can change which papers appear near the top.
- The language model used for synthesis may change without a prominent notice.
- Free and paid accounts may search different amounts of material or expose different evidence.
- The same product may return a paper list, a narrative answer or an upgrade prompt depending on remaining credits.
A useful evaluation therefore needs repeated runs, preserved failures and a record of the account conditions. Without those controls, a reviewer can unintentionally publish a result that ordinary users cannot reproduce.
The seven-step repeatability test
1. Define a question with a checkable target
A vague prompt such as “tell me about retrieval practice” makes relevance difficult to judge. Use a question with a population, intervention or concept, comparison where appropriate, and a result you can verify.
For example:
What controlled studies published since 2015 examine retrieval practice in undergraduate education, and what outcomes do they report?
Record the exact wording before opening any tool. Do not improve the prompt for one product unless you apply the same change to every product and log it as a new test.
2. Start from comparable account conditions
Write down whether each test uses a free account, trial, subscription or institutional access. Also record remaining credits, visible search-depth settings and any features blocked behind an upgrade.
This matters because “free version tested” is often too vague. A free account with its monthly allowance intact is not equivalent to the same account after the allowance has been exhausted.
3. Run the identical task at least three times
Use a clean session where possible and run the same prompt three times. Preserve the time, result URL, visible result count and any status message. Do not discard a weak run and keep repeating until the product looks good.
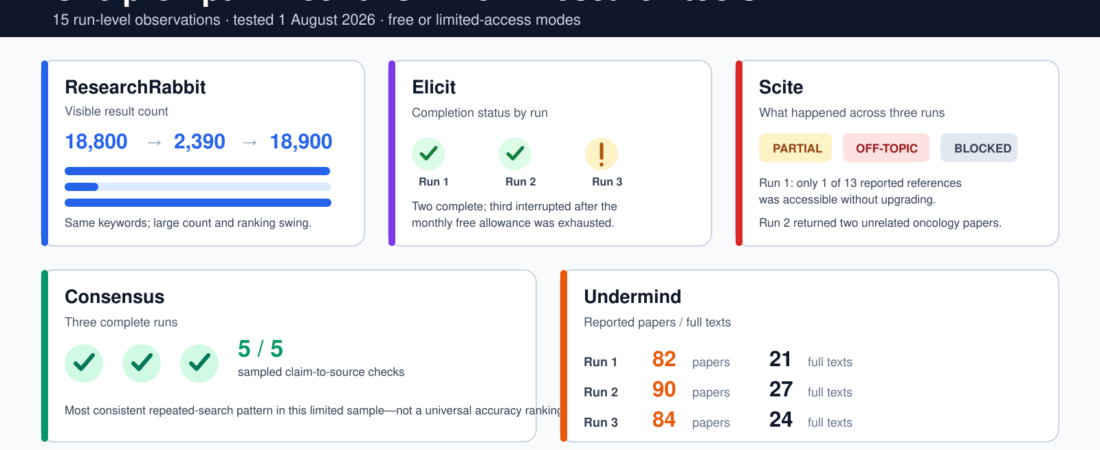
In our benchmark, the visible ResearchRabbit result count shifted from approximately 18,800 to 2,390 and then 18,900 across matched runs. That does not automatically make the tool poor, but it is material evidence about what a user may encounter and should be explained before drawing a verdict.
4. Separate retrieval from presentation
A fluent summary and a strong evidence set are different things. Score them separately.
| Layer | Question to ask | Evidence to retain |
|---|---|---|
| Retrieval | Did it find relevant records? | Titles, identifiers, result count and export |
| Traceability | Can every important claim be checked? | Claim-to-source pairs, DOI and cited passage |
| Synthesis | Does the answer represent the retrieved studies accurately? | Saved answer and manual verification notes |
| Access | Could the promised evidence actually be opened or exported? | Paywalls, credit messages and export files |
A product can write the most readable answer while retrieving an incomplete evidence set. Another can return a useful paper list while producing a weak summary. Combining these layers into one vague “quality” score hides the difference.
5. Check a sample of claims against the papers
Select at least five important factual claims from each generated answer. For every claim, confirm:
- The cited paper exists.
- The title, authors, year and DOI match.
- The paper actually supports the claim.
- The claim does not overstate correlation as causation.
- The cited source is not merely repeating another source.
Mark each claim as supported, partly supported, contradicted or unverifiable. A citation badge is not proof that the surrounding sentence is accurate.
6. Keep failures in the dataset
Failures are often more useful than ideal screenshots. In our matched tests, one Scite run produced an answer grounded in unrelated oncology material, while another was blocked by a trial prompt. Elicit later exhausted its monthly free allowance. These outcomes changed the practical comparison even though the products had also produced useful results.
Use a simple failure log with the prompt, timestamp, account tier, observed behaviour, screenshot or URL, and whether retrying changed the result. Never replace the original failure with the successful retry.
7. Delay the winner until the evidence is comparable
Do not publish a ranked winner when one product received three full searches and another received only one limited result. Mark criteria as untested rather than converting missing evidence into a zero.
A defensible conclusion might be:
- Most consistent in these three runs, rather than “most accurate”.
- Strongest accessible export on the tested free tier, rather than “best for systematic reviews”.
- Promising but not comparable under current access limits, rather than forcing a numerical rank.
What our first repeat-run benchmark found
The aim of our initial benchmark was not to manufacture a universal winner. It was to see how much the user experience changed when the same research task was repeated and the failures were preserved.
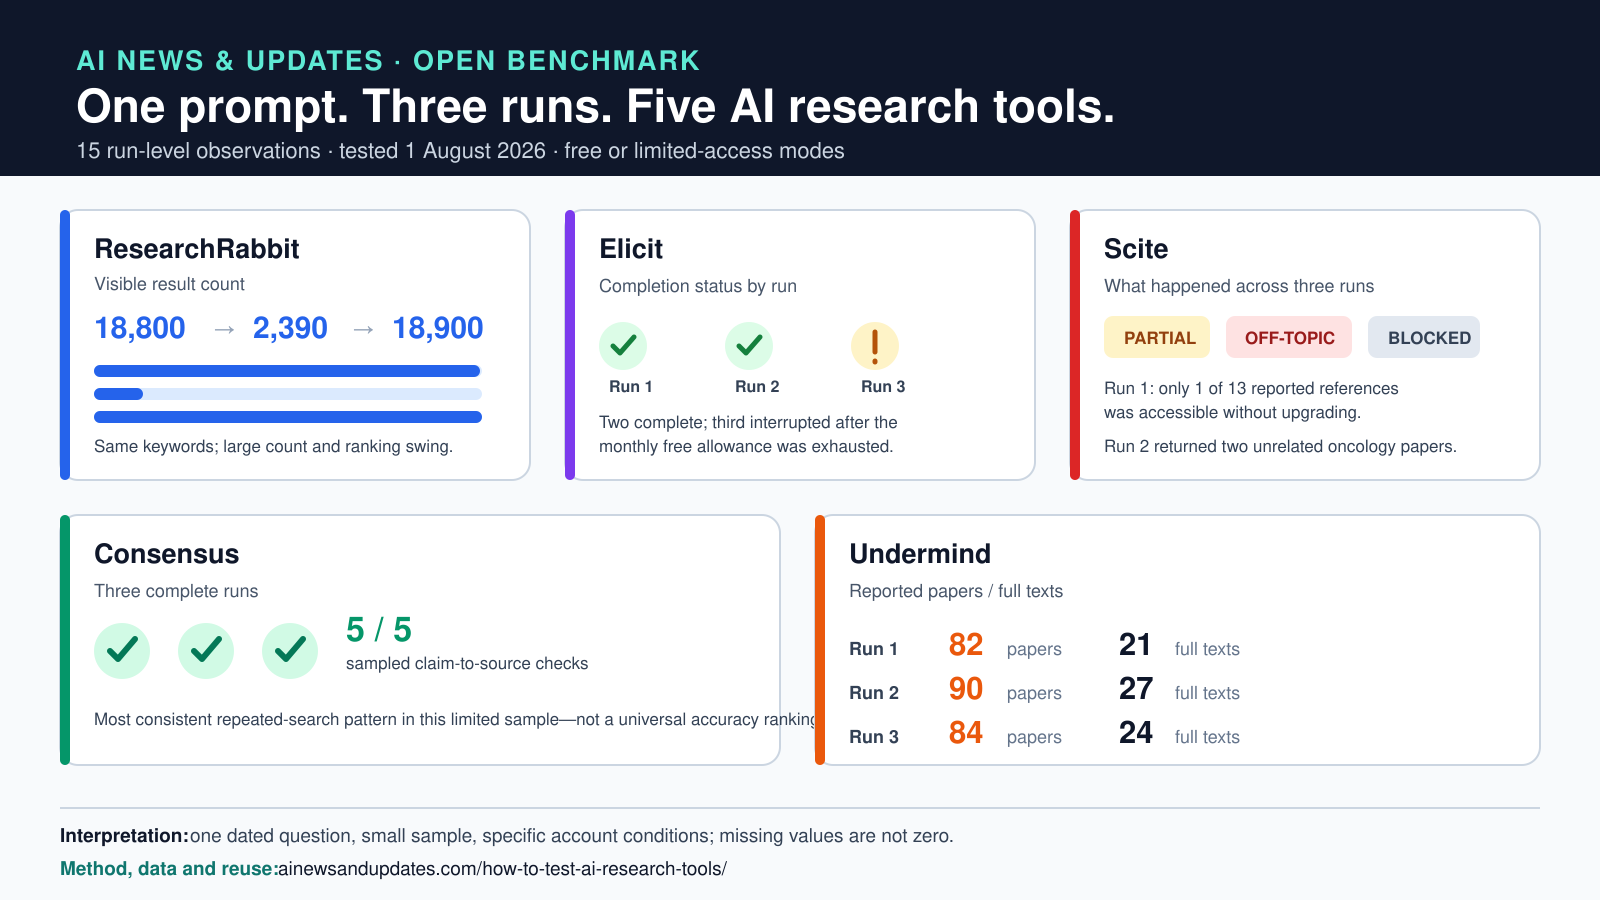
- ResearchRabbit showed a large shift in visible result counts across matched runs.
- Elicit provided useful structured evidence but the tested free allowance was exhausted before every planned task could be completed.
- Scite exposed important access limitations and one unrelated grounded response during the test sequence.
- Consensus was the most consistent of the repeated searches in this limited sample, and five sampled claim-to-source checks matched the cited paper records.
- Undermind returned 82, 90 and 84 papers across three runs, including 21, 27 and 24 full texts respectively.
These are observations from a specific August 2026 test using particular account conditions. They are not permanent product facts. Interfaces, models, indexes and access limits can change, which is exactly why the test record includes dates and account tiers.
Open data and reusable downloads:
- Download the CSV dataset — all 15 run-level observations in an open tabular format.
- Download the XLSX workbook — spreadsheet-ready evidence for review and teaching.
- Download the reusable DOCX worksheet — a blank template for matched repeat runs.
- Download the CITATION.cff file — machine-readable citation metadata.
- View the complete repository — field definitions, methodology, limitations and version history.
Reuse is permitted with attribution to AI News & Updates and a link to this canonical methodology.
All 15 run-level observations
The table below makes the complete run-level result visible on the canonical page so readers can inspect failures and access limits without relying on a summary score. Blank cells mean the product did not expose that metric; they do not mean zero.
| Tool | Run | Status | Reported results | Accessible | Full text | Elapsed | Observed outcome |
|---|---|---|---|---|---|---|---|
| ResearchRabbit | 1 | Complete | 18,800 | — | — | 0.2 min | Broad discovery set mixed reviews, non-comparators and plausible primary studies. |
| ResearchRabbit | 2 | Complete | 2,390 | — | — | 0.2 min | Identical keywords returned far fewer results and different top rankings. |
| ResearchRabbit | 3 | Complete | 18,900 | — | — | 0.2 min | Result volume returned close to run 1, confirming a large between-run swing. |
| Elicit | 1 | Complete | 5 | 5 | — | 4 min | Four verified eligible studies and one explicitly incomplete record. |
| Elicit | 2 | Complete | 4 | 4 | — | 4 min | DOI-linked table retained null and long-delay boundary cases. |
| Elicit | 3 | Partial | 7 | 7 | — | 4 min | Monthly free allowance ended before the final response completed. |
| Scite | 1 | Partial | 13 | 1 | — | 0.5 min | Only one of 13 reported references was exposed without upgrading. |
| Scite | 2 | Complete | 2 | 2 | — | 0.3 min | The repeated prompt retrieved two unrelated oncology papers. |
| Scite | 3 | Blocked | — | 0 | — | 0.1 min | A mandatory seven-day trial prompt blocked the run. |
| Consensus | 1 | Complete | — | — | — | 0.5 min | Five sampled claims matched paper records and DOIs. |
| Consensus | 2 | Complete | — | — | — | 0.8 min | Eligible-study extraction included a qualified conclusion and disagreement. |
| Consensus | 3 | Complete | — | — | — | 0.8 min | Separated the dominant finding from conditional and restudy-favouring evidence. |
| Undermind | 1 | Complete | 82 | 82 | 21 | 0.8 min | Ranked papers and DOI links; the summary did not visibly surface disagreement. |
| Undermind | 2 | Complete | 90 | 90 | 27 | 1.4 min | The matched search completed and its CSV export was preserved. |
| Undermind | 3 | Complete | 84 | 84 | 24 | 1.4 min | The third run noted less-uniform evidence for some implementations. |
Dataset scope: one higher-education research question, five products, three matched runs each, tested on 1 August 2026 using the disclosed free or limited-access mode. These observations describe the tested conditions; they do not establish permanent product rankings.
Cite or reuse this benchmark
Libraries, researchers and publishers may cite the benchmark, reuse the infographic, or adapt the seven-step checklist with attribution. Please link to this page as the canonical methodology so readers can inspect the test conditions and limitations.
Suggested citation:
AI News & Updates Editorial Team. (2026). How to Test AI Research Tools for Repeatable Results. AI News & Updates. https://ainewsandupdates.com/how-to-test-ai-research-tools/
Reusable graphic: Download the 1600×900 PNG. Credit: “AI News & Updates, AI Research Assistant Repeatability Benchmark 2026,” with a link to this methodology.
Copy-paste embed code:
<figure><a href="https://ainewsandupdates.com/how-to-test-ai-research-tools/"><img src="https://ainewsandupdates.com/wp-content/uploads/2026/08/ai-research-tool-repeatability-benchmark-15-runs.png" alt="AI research assistant repeatability benchmark: 15 matched runs across five tools" width="1600" height="900"></a><figcaption>Source: AI News & Updates, AI Research Assistant Repeatability Benchmark 2026.</figcaption></figure>This code displays the full-size graphic, links the image to the canonical methodology and includes a plain-language source caption. Publishers may resize the image while preserving the attribution and link.
Editorial contact: hello@ainewsandupdates.com
A scoring framework that avoids false precision
Use a score only after documenting the underlying evidence. Our framework separates seven criteria:
- Task completion
- Result relevance
- Evidence traceability
- Repeatability
- Failure recovery
- Privacy and security documentation
- Price-to-output value
Each criterion should link to an observation, export, source document or claim check. Blank criteria should remain blank until tested. A decimal score without an evidence trail creates the appearance of precision without the substance.
You can download the workbook and compact reference from our transparent AI-tool review methodology.
Testing a commercial workflow rather than literature search? Use the 12-test AI tool trial checklist for small businesses. It applies the same repeat-and-log principle to workflow timing, correction rates, privacy, pricing, integrations and exit risk.
How to use AI research assistants safely
- Use them to discover terminology, seed papers and possible lines of enquiry.
- Verify important claims in the underlying paper, not only the generated summary.
- Export records early because access limits and results may change.
- Keep a traditional database-search record for systematic work.
- Do not upload confidential, personal or unpublished material before checking current data-handling terms.
- Record the tool, date, account tier, settings and prompt when the work must be auditable.
Frequently asked questions
How many times should an AI research search be repeated?
Three matched runs are a practical minimum for detecting obvious instability. More runs may be necessary when the result is safety-critical, the system is highly variable or a formal comparison is being published.
Can an AI research assistant replace a systematic database search?
Not on the strength of a generated report alone. Systematic work requires documented coverage, search strings, inclusion decisions and reproducible records. AI tools may supplement parts of that workflow, but their retrieval and ranking can be less transparent.
What is the most important metric?
There is no single universal metric. For evidence-based work, traceability and repeatability are more useful than writing style. For exploratory discovery, relevance and coverage may matter more. Define the intended task before choosing weights.
Should failed searches affect a review score?
Yes. A failed or unrelated run is part of the real user experience. Log it, investigate it and report whether retrying resolved the problem, but do not erase it from the comparison.
Methodology note: This article reports observations from the AI News & Updates repeatability benchmark conducted in August 2026. No vendor paid for inclusion or was offered a verdict change in exchange for a correction or link.